How to Reduce LLM API Costs Without Losing Quality
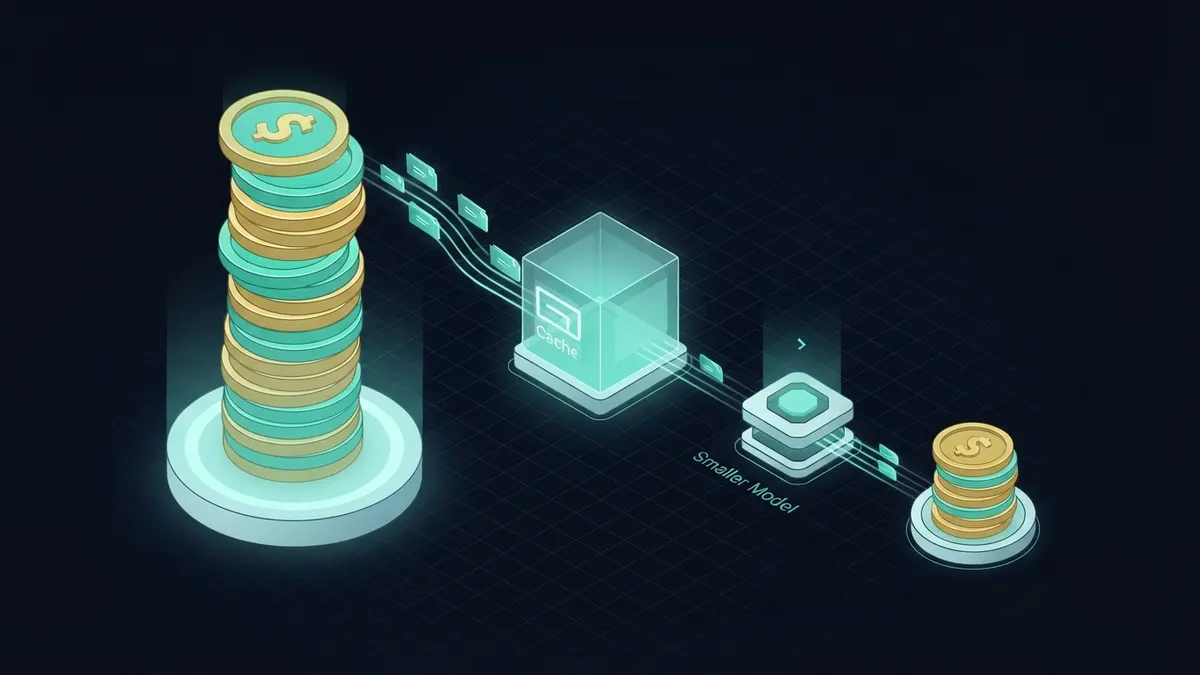
Measure cost per feature first, then cut in this order: trim context and output length, use provider prompt caching for repeated prefixes, cache whole responses where safe, route easy requests to smaller models, send non-urgent work through batch APIs, and re-run your evaluation suite after each change.
Where does LLM spend actually come from?
API bills are driven by input tokens, output tokens and the price tier of the model processing them. Input tokens often dominate in retrieval and agent apps, because every turn resends the system prompt, tool definitions, retrieved documents and the growing conversation.
Agents multiply this. Each step of a tool-using loop is a new request that carries the whole history, so a ten-step task can cost many times a single chat reply. Output tokens are usually priced higher per token than input, which makes verbose answers and long reasoning expensive too.
Before optimizing, tag every request with the feature, customer and model that produced it. Without that attribution you will spend a week shaving a prompt that accounts for a small share of the bill.
Also separate fixed from variable spend. Embeddings, evaluation runs and background jobs are easy to overlook because no user sees them, yet they can grow quietly as your data grows.
Which cost-reduction techniques work best?
The techniques below are ordered roughly from least to most engineering effort. Most teams get meaningful savings from the first three before touching model choice.
| Technique | How it saves | Effort | Risk to quality |
|---|---|---|---|
| Trim context | Fewer input tokens per request | Low | Low if retrieval stays relevant |
| Limit output | Fewer output tokens | Low | Answers may get cut off if limits are too tight |
| Provider prompt caching | Repeated prompt prefixes billed at a reduced rate | Low to medium | None when used correctly |
| Response caching | Skips the model entirely for repeated requests | Medium | Stale or wrong answers if keys are too loose |
| Model routing | Easy requests go to cheaper models | Medium | Misrouted hard requests get worse answers |
| Batch APIs | Discounted asynchronous processing | Low to medium | Results are not immediate |
| Self-hosting open models | Replaces per-token fees with infrastructure cost | High | Operations burden and possible quality gap |
How does prompt caching reduce costs?
Major providers, including Anthropic and OpenAI, offer prompt caching: when the start of a request matches a recently processed prefix, that part is billed at a lower rate and usually processed faster. The details, such as minimum length, cache lifetime and whether you mark cache points explicitly, differ by provider, so read the current documentation.
To benefit, put stable content first and variable content last. System prompt, tool definitions and long reference documents go at the top; the user’s latest message goes at the end. Anything that changes per request near the top, such as a timestamp, breaks the cache for everything after it.
Check the usage fields in API responses to confirm cache hits. It is common to set up caching and then lose it silently because a template inserts a request ID at the start.
Caching pays off most for long, stable prefixes that many requests share: a large system prompt, a product manual used for every question, or a codebase summary reused across an agent’s steps. Short prompts with little shared content see much smaller gains.
When should you cache whole responses?
Exact-match response caching is safe and simple: hash the model, parameters and full input, and reuse the stored output. It works well for classification, extraction from identical documents and repeated FAQ-style queries.
Semantic caching, which reuses answers for similar rather than identical questions, saves more but is riskier. Two questions can be close in embedding space and still need different answers, such as questions about different plans or dates. Use it only with a strict similarity threshold and never for personalized or account-specific answers.
How do you route requests to smaller models?
Many requests do not need the strongest model. Classification, short extraction, rewriting and simple lookups often work well on a small, cheap model, while complex reasoning and long-form writing benefit from a larger one.
Routing can be as simple as rules by feature, or a small classifier that estimates difficulty. Open-source gateways such as LiteLLM give you one API across providers and make switching models per route a configuration change. Research projects such as RouteLLM explore learned routers.
A cascade is another option: try the small model first, check the output with a validator or confidence signal, and escalate to the large model only when it fails. This needs a reliable check, or you will ship the small model’s mistakes.
Re-evaluate routes when new models arrive. Small models improve quickly, and a route that needed a large model last year may not need one now.
How do you cut costs step by step?
- Instrument every request with feature, model, input tokens, output tokens, cached tokens and latency.
- Rank features by monthly cost and start with the top one or two.
- Remove unused instructions, duplicate examples and tool definitions the feature never needs.
- Tighten retrieval so fewer, better chunks go into each request.
- Set explicit maximum output lengths and ask for concise formats where users do not need prose.
- Restructure prompts for provider caching and verify cache hits in usage data.
- Move offline jobs such as nightly summaries, backfills and evaluations to batch endpoints.
- Try a smaller model on each route, keep it only where your evaluation suite shows acceptable quality.
Where does it break? Common mistakes
- Optimizing cost without an evaluation suite, so quality drops go unnoticed until users complain.
- Letting agent conversations grow forever instead of summarizing or dropping old tool results.
- Semantic caching of personalized answers, which can show one customer another customer’s information.
- Retries without limits, where a timeout loop quietly multiplies spend.
- No per-customer budgets, so a single heavy user or abusive script dominates the bill.
- Comparing models on price per token alone, ignoring that a cheaper model may need more tokens or more retries to finish the task.
How do you control agent and conversation costs?
Long conversations and multi-step agents are where bills grow fastest, because every request resends everything before it. Summarize older turns once a conversation passes a length threshold, and keep only the summary plus the most recent messages.
Tool results are often the largest items in an agent’s history. Store full results outside the context and give the model a short digest with an ID it can use to fetch details if needed. Drop results that are no longer relevant to the current step.
Set budgets at several levels: per request, per task and per customer per month. When a task hits its budget, stop and report instead of silently continuing. Budgets turn runaway loops from a surprise invoice into a logged error.
Finally, review reasoning settings. Models with adjustable thinking or reasoning effort can spend many output tokens on simple tasks; use lower settings where your evaluation shows no quality loss.
Is self-hosting an open model cheaper?
Sometimes. Self-hosting turns per-token fees into GPU and operations costs. It tends to pay off with steady, high volume, strict data requirements, or tasks where a smaller fine-tuned model matches a large hosted one.
At low or spiky volume, idle GPUs are expensive and hosted APIs usually win. Include engineering time for serving, monitoring, upgrades and on-call in the comparison, not only hardware prices. Serving engines such as vLLM and llama.cpp make self-hosting practical, but they do not make it free.
Frequently asked questions
- What is the fastest way to lower my LLM bill?
- Usually trimming what you send. Remove unused instructions and tools, retrieve fewer but better chunks, cap output length, and restructure prompts so provider caching applies to the stable prefix. These changes take hours rather than weeks and rarely hurt quality when you check them against an evaluation set.
- Does prompt caching change model outputs?
- No. Provider prompt caching reuses the processing of an identical prefix; the model still generates a fresh response. It is different from response caching, where you store and reuse a previous answer. Response caching can return stale or mismatched answers if your cache keys are too loose.
- When are batch APIs a good fit?
- Whenever the user is not waiting: nightly reports, document backfills, bulk classification, embeddings and evaluation runs. Batch endpoints from major providers process requests asynchronously at a discount. Check each provider’s current pricing, size limits and completion window before you move a workload there.
- Are open-source AI gateways worth using for cost control?
- Often yes. A gateway such as LiteLLM centralizes provider keys, logs usage per team or feature, enforces budgets and lets you swap or route models through configuration. The trade-off is another service to run and secure, so keep it simple and monitored.